NVIDIA B300 default
Blackwell Ultra silicon, dedicated to your reservation.
Dedicated capacity for large-scale workloads. NVIDIA B300 Nodes built to Reference Architecture and sovereign by nature.
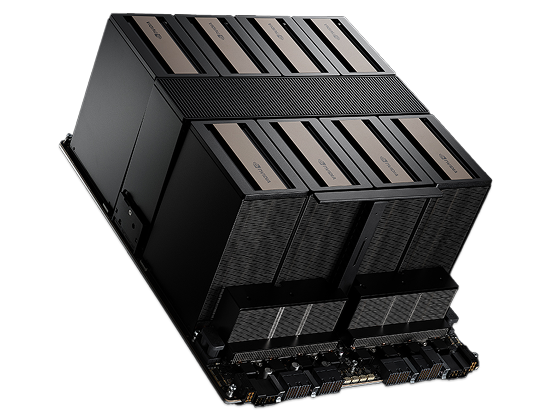
Reserved multi-node NVIDIA B300 (Blackwell Ultra) clusters built to the NVIDIA Reference Architecture. Reserve for up to 5 years for lower cost-per-hour compute.
Amaze offers five reservable NVIDIA B300 (Blackwell Ultra) clusters in Sydney, from 8 to 1,024 GPUs each, from $5.00 per GPU-hour on 1 to 5 year terms, with the first cluster ready for service immediately.
| GPU model | Scale | Location | GPU memory | Cluster memory | Networking | Price and Term | Ready For Service | |
|---|---|---|---|---|---|---|---|---|
| NVIDIA B300 | 1,024 GPUs 128 nodes | Sydney, Australia | 288GB | 288TB | NVIDIA RA 800Gbps | From $5.00 / Hour 30% Prepayment 5 Years | Feb 2027 | Contact Sales → |
| NVIDIA B300 | 1,024 GPUs 128 nodes | Sydney, Australia | 288GB | 288TB | NVIDIA RA 800Gbps | From $5.00 / Hour 30% Prepayment 5 Years | Feb 2027 | Contact Sales → |
| NVIDIA B300 | 128 GPUs 16 nodes | Sydney, Australia | 288GB | 36TB | NVIDIA RA 800Gbps | From $6.80 / Hour 30% Prepayment 3 Years | Nov 2026 | Contact Sales → |
| NVIDIA B300 | 128 GPUs 16 nodes | Sydney, Australia | 288GB | 36TB | NVIDIA RA 800Gbps | From $6.80 / Hour 30% Prepayment 3 Years | Dec 2026 | Contact Sales → |
| NVIDIA B300 | 8 GPUs 1 node | Sydney, Australia | 288GB | 2.3TB | NVIDIA RA 800Gbps | From $7.50 / Hour 20% Prepayment 1 Year | Immediate | Contact Sales → |
All prices listed in USD. AUD pricing provided on quote.
Prices are indicative starting figures. Quotes are contract-term, memory-configuration and payment-structure specific. Speak to our solution architects to create a tailored quote based on your requirements.
Predictable per-node performance on NVIDIA B300 (Blackwell Ultra) silicon built to the NVIDIA Reference Architecture. Dedicated capacity under an Australian-governed control plane, root access available.
Blackwell Ultra silicon, dedicated to your reservation.
Purpose-built cluster fabric for collective ops.
Full OS-level control on request for regulated workloads.
Australian-controlled infrastructure, Australian jurisdiction.
Silicon count, fabric and topology sized to the workload.
8 latest-generation NVIDIA B300 (Blackwell Ultra) GPUs per node.
Carrier-grade Australian backbone.
Australian-based on-call, 24×7.
Reserved clusters run on enterprise networking built to lower latency and minimise errors.
Seven families, dozens of sizes, one Australian API. Pick the model, call the endpoint, ship the feature.
Five things make Amaze reserved GPU clusters different from a generic public-cloud GPU instance.
All self-service. No tickets, no offshore approvals, no time-zone tax.
Workload sizing, topology, contract terms, all Australian.
NVIDIA B300 GPU nodes on the NVIDIA Reference Architecture, Intel Xeon CPU nodes, or both. Root access available on request.
Cluster live in days, not quarters. Same API as on-demand.
Foundation-model training, large-scale batch, scientific compute.
GPU clusters fit inside the broader HPC overview, sovereign supercomputing, VFX rendering, scientific compute, all on the same Australian backbone.
Talk to an Australian solution architect about the silicon, the topology, and the contract terms.
IPNG has consolidated into the parent company Amaze Intelligence. This means the same Australian IP transit, fibre and business internet services are now available through Amaze Intelligence, alongside our broader Sovereign AI, Cloud and Data services.
Existing IPNG customers, services, contracts and support arrangements are unaffected. You're now on the Amaze IP Transit page, explore the full networking range or talk to our team.
Need to reach the IPNG team? Contact Amaze — your account is in our system.
Wholesale Cloud has consolidated into the parent company Amaze Intelligence. Wholesale services can now be accessed through the new Amaze Partner Program, which requires a new account. The program offers Refer and Resell tiers, with improved pricing, new product offerings, and full access to Amaze's Sovereign AI, Cloud and Data services.
Existing Wholesale Cloud resellers, contracts and end-customer services are unaffected. Apply for Tier 2 to access the new program, or choose to remain on your grandfathered plans, as no action is necessary.
Existing Wholesale Cloud reseller? Contact Amaze, your reseller arrangements carry across.